

What we are reading
Other people’s writing on the parts of AI engineering we work in, pulled from dev.to and Hacker News and refreshed every day. Anything older than a month drops off. Every link goes to the original, and the author’s name is on it.
Today’s pick
Anthropic S-1
261 articles from the last 30 days, page 1 of 22
ControlArena: the monitored model could shape its monitor’s prompt
In AI control experiments, a trusted monitor reads what an untrusted model did and scores how...
KV Cache Wars: How Compaction, Quantization, and a Rust Rewrite Are Redefining LLM Serving Economics
This week in LLM inference: KV-cache compaction and quantization breakthroughs, vLLM's GB300-scale DeepSeek benchmarks, and Anthropic's Rust rewrite.
How to write tool descriptions for AI agents
Tool descriptions for AI agents decide whether an agent uses your tool correctly. Eight rules, a TypeScript MCP example and an automated check for your CI.
Asking my CI "why did that fail?": GitHub Actions cognee
I wanted to ask my CI a plain question: "which workflows failed recently, and why?" So I built a...
What Is LLM Inference? What Happens Between Your Prompt and the AI's Answer
This guide was first published on saurabhbhayana.com. Imagine spending hundreds of millions of...
I tested my agent sandbox next to a prompt-injection guardrail and found a way around its approvals
Approval prompts are the last line of most agent setups. The agent wants to send data out, a human...
### ABLITERAX 规范页面的核心模块与交互
html <!DOCTYPE html> <html lang="zh-CN"> <head> <meta...
Nobody Prompts for a Spending Limit: How to Stop Your AI App From Burning Money Overnight
A client of mine once left an automated AI app running unsupervised for one day. The app generated...
# ABLITERAX — Design and Reference Implementation
ABLITERAX — Design and Reference Implementation Below is a working, testable first-version...
I Reproduced OpenAI's Agent Safety-Alert Evasion on a Free Model
On October 20, 2026, OpenAI published something unusual on its own misalignment-reports page: two...
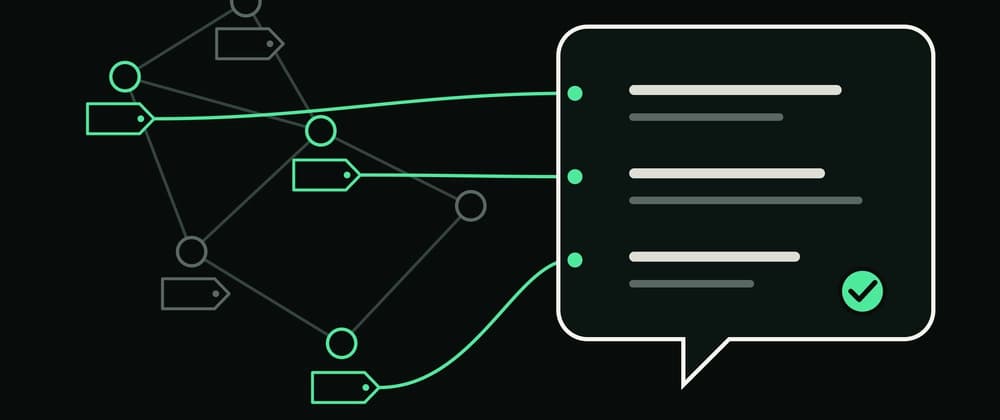
Grounded answers: how Graphify tags what it knows
Confidence tags label every Graphify edge EXTRACTED, INFERRED, or AMBIGUOUS, so an agent can see what was parsed and what was guessed.
Why graphs beat vectors for agent memory
A code graph vs a vector database keeps the relationships for the next session, instead of searching similar text again.